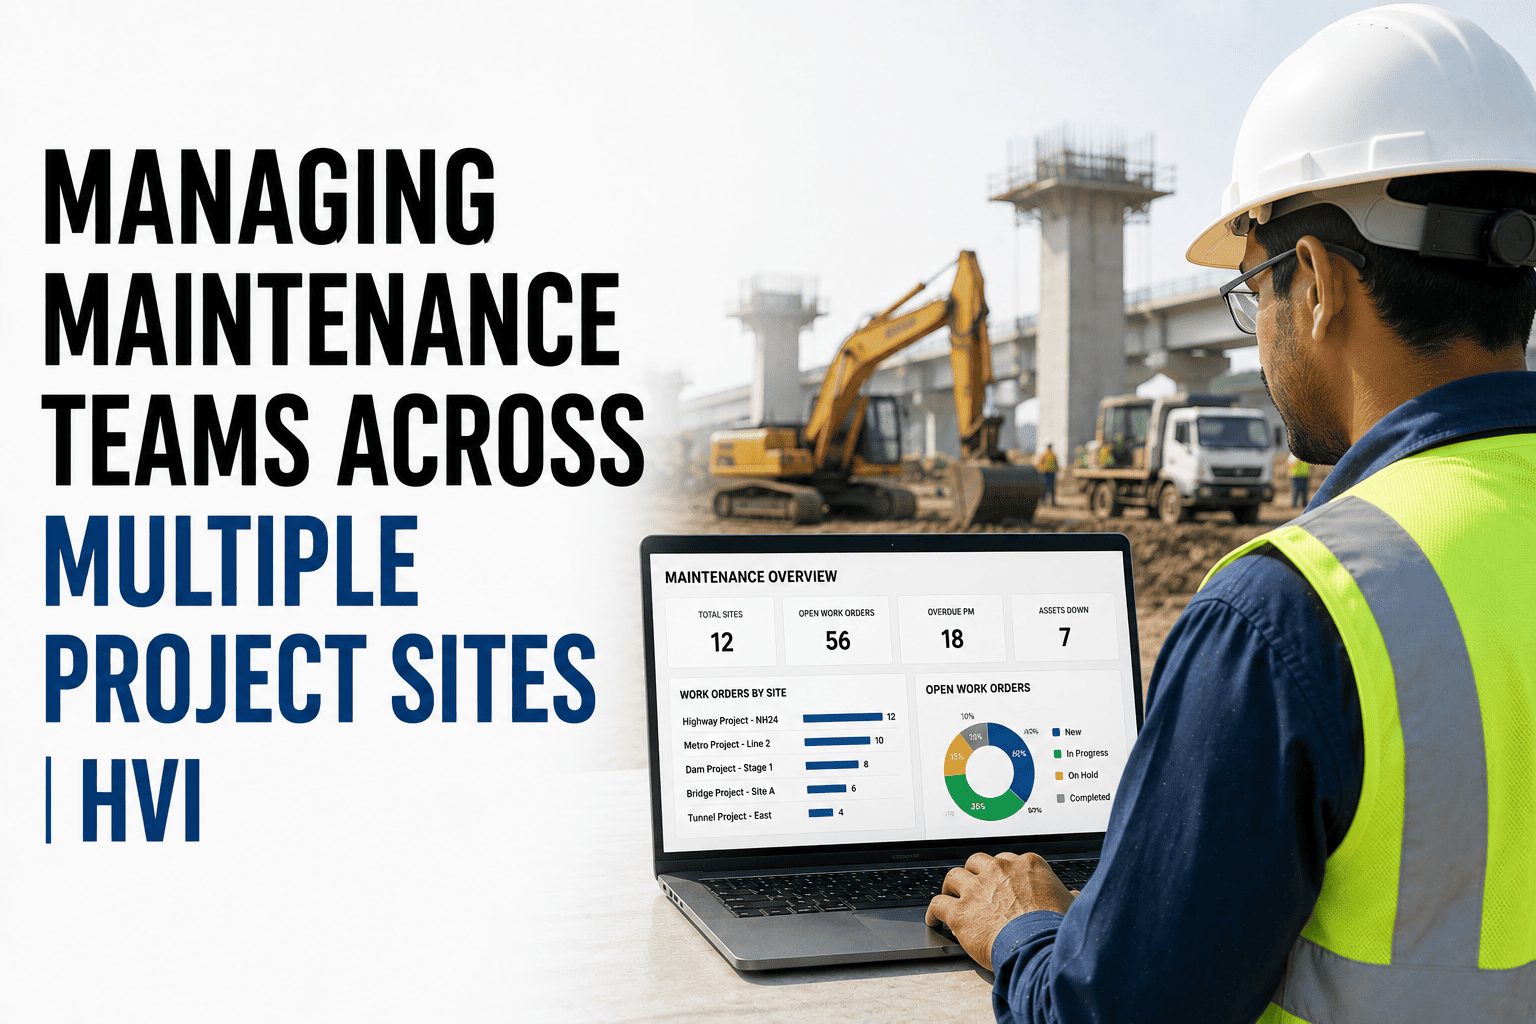
Managing maintenance across several sites is not a scaled-up version of managing one. At a single site a maintenance head walks the yard and knows within a morning what is going on. Across five sites that knowledge has to arrive through records, and whatever the records do not carry simply does not reach you. Teams adapt locally, standards drift apart without anyone deciding to change them, and problems that would have been obvious in person surface weeks later in a report. The work is deciding what must be identical everywhere and what should be left to the site, and you can think that through for your own operation in a free 30-minute session.
Managing Maintenance Teams You Cannot Walk Past
What distance actually costs, which standards must hold across every site, and the contact rhythm that keeps distributed teams aligned.
Four Things Distance Does to a Maintenance Operation
Standards drift without anyone deciding
Each site adapts the process to its own conditions, reasonably, one small change at a time. Two years later the sites are running different systems that share a name.
Knowledge stays where it was earned
A fix worked out at one site is rediscovered at three others, because nothing carried it across. This is the most expensive and least visible cost of distance.
Problems surface late
A pattern obvious to the people on site takes weeks to appear centrally, by which point it has generated cost rather than a warning.
Sites optimise for themselves
Rational locally, expensive overall. A site holding its own spares buffer makes sense to that site and ties up capital across the group.
Standardise These, Leave Those Alone
The common mistake is trying to standardise everything, which sites resist because much of it genuinely should differ. This is the split that tends to hold.
Standardise definitions and data. Leave execution to the people doing it.
Get the Same Picture From Every Site
Common definitions and one record structure across sites, with local flexibility on how the work actually gets done.
A Contact Rhythm That Works
Daily — data, not calls
Completion rates, open critical defects, and machines held. Reviewed rather than requested, so nobody spends their morning assembling a status update.
Weekly — a short conversation per site
Fifteen minutes on exceptions only, with the data already read beforehand. Long enough to catch drift, short enough to actually happen every week.
Monthly — comparison across sites
Where one site differs sharply from the others on the same equipment. Differences are questions, not verdicts, and often reveal a better practice worth copying.
Quarterly — visit in person
No record substitutes entirely for standing in the workshop. The purpose is what the data cannot show, not repeating what it already did.
Frequently Asked Questions
How do we stop sites resisting standardisation?
Usually by narrowing it. Resistance is often justified, because teams are being asked to change things that genuinely should differ. Standardising definitions and data while leaving execution local removes most of the objection. You can work through where your own line sits on a call with our team.
Should every site report the same metrics?
Yes for the core set, or comparison is impossible. Sites can track additional measures that matter locally, provided the shared ones are defined identically.
How do we move knowledge between sites?
Largely by making defect and repair history visible across the group, so a fault someone has already solved is searchable rather than rediscovered. Formal knowledge sharing rarely survives busy periods; searchable records do.
Is a site visit still necessary if the data is good?
Yes. Records show what happened, not how the team is doing or what they have stopped bothering to report. Both matter and only one is visible remotely.
What should we fix first?
Common definitions, particularly what counts as a critical defect. Until that is identical, no cross-site comparison means anything. Start with a free trial on two sites.
Same Definitions, Local Execution, Regular Rhythm
Fix what a critical defect means and how records are structured across every site, leave timing and local practice to the teams, and keep a contact rhythm short enough that it survives a busy month.